From Prismml · · 2m
Bonsai 2 27B: 9x smaller, nearly full power
PrismML's new compressed model runs advanced AI on local devices without meaningful capability loss.
In brief
PrismML's new compressed model runs advanced AI on local devices without meaningful capability loss. You can now run a capable 27-billion-parameter AI model on your laptop or phone at 5.9GB with 98.2% of the performance of the full-size version. Originally reported by Prismml.
Meet Bonsai 2 27B
PrismML released Ternary Bonsai 2 27B, a compressed AI model based on Qwen3.8 27B that runs efficiently on local devices. It uses ternary weights (−1, 0, +1) to achieve just 5.9GB total size.
9x smaller, 98% capable
Compared to the full-precision Qwen3.8 27B, Bonsai 2 27B is more than 9 times smaller while retaining 98.2% of aggregate benchmark performance. This level of compression becomes a practical deployment unlock.
“compression becomes a deployment unlock: nearly the same capability, in a footprint that can run in far more places.”
Stronger reasoning and coding
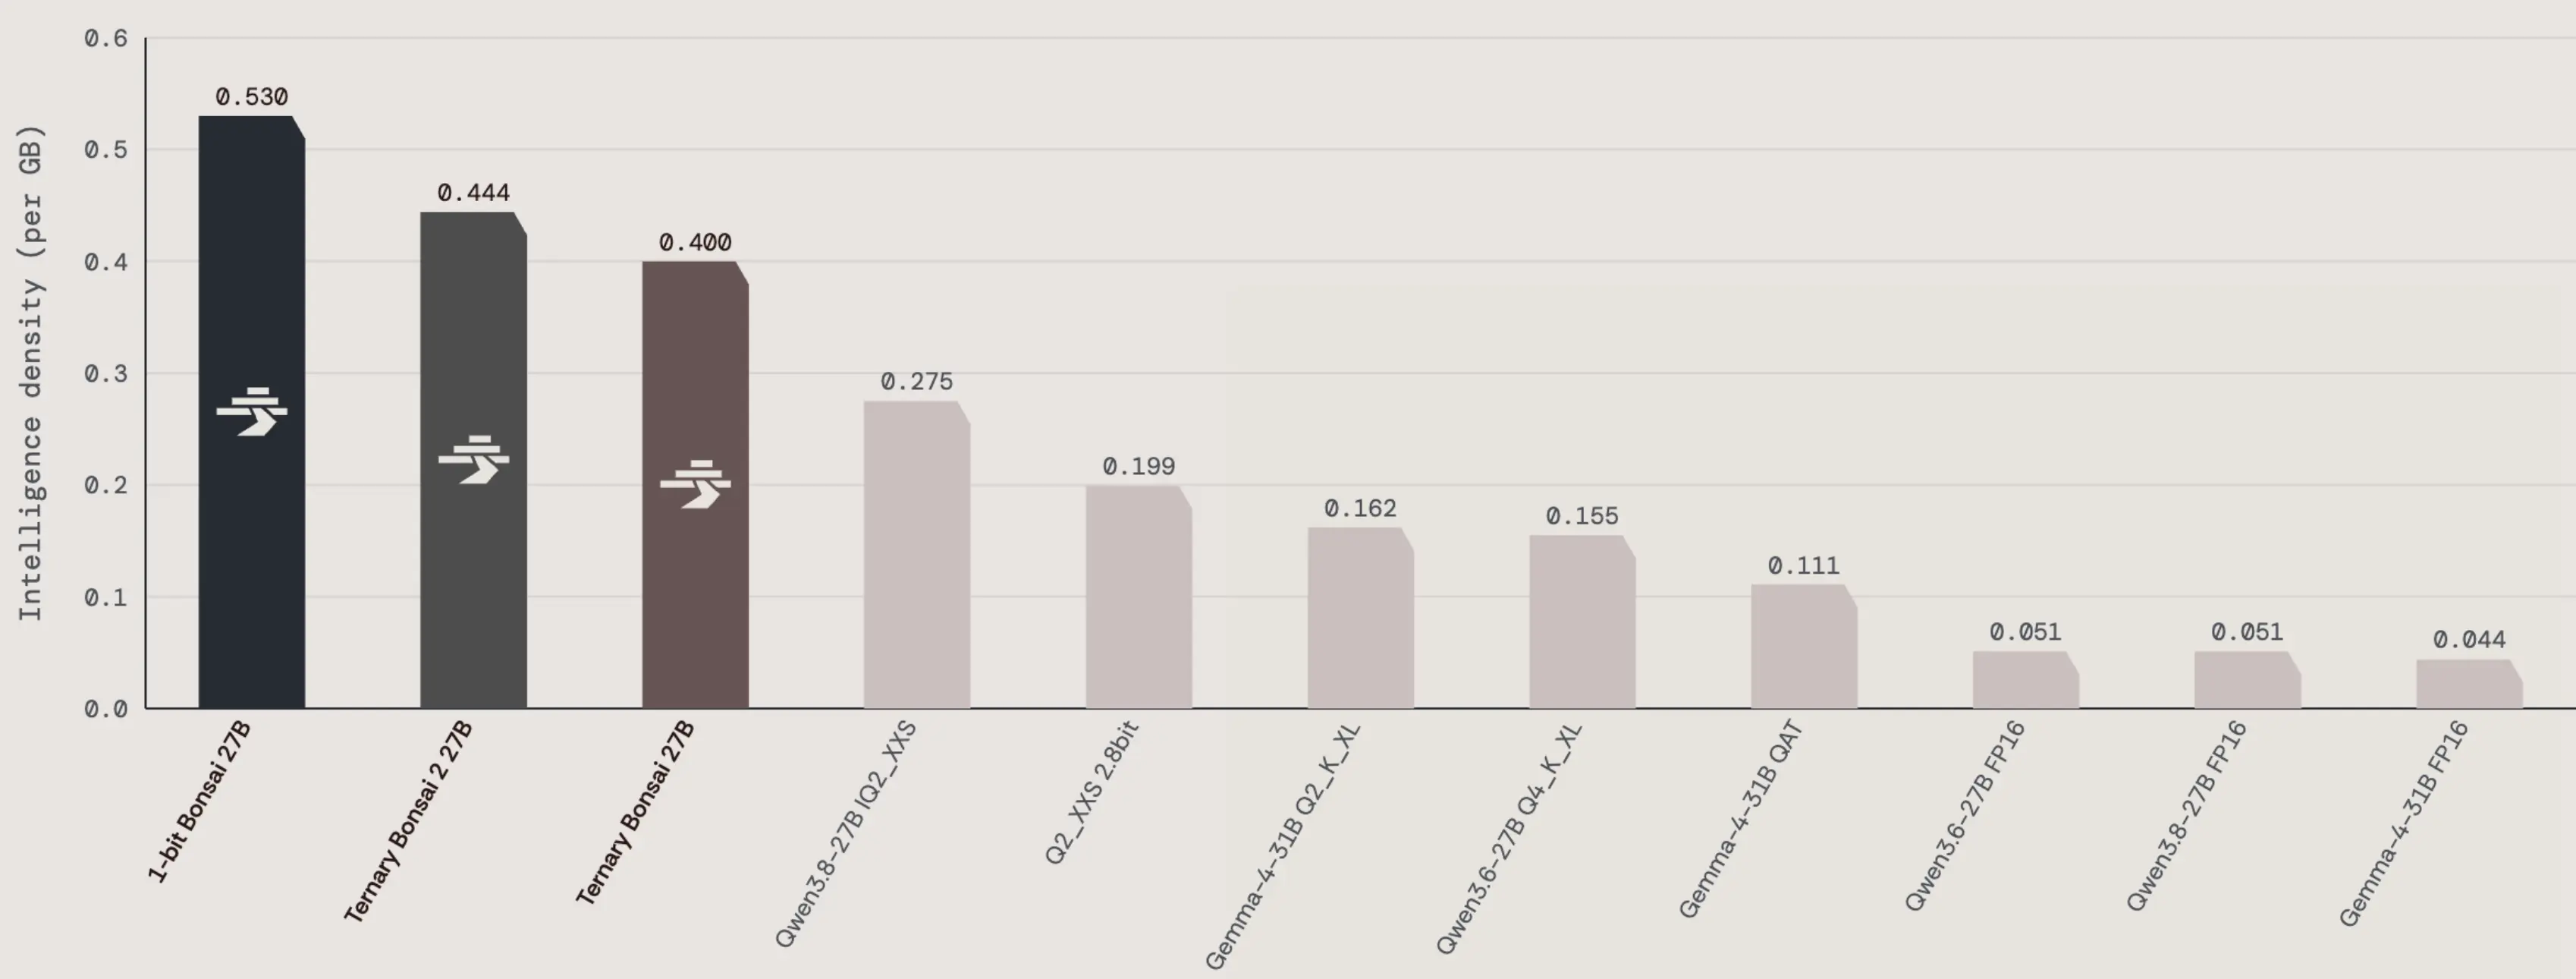
Bonsai 2 27B improves on the first generation with better reasoning, coding, vision, and agentic capabilities. It scores 83.9 overall, retaining 98.2% of the full model's performance across benchmarks.
Where compression matters most
Coding agents, tool-use systems, and multimodal workflows are sensitive to model degradation because small errors compound. Bonsai 2 27B preserves performance in exactly these areas while using a fraction of the memory.
Fast enough for real work
Bonsai 2 27B reaches 143 tokens per second on NVIDIA RTX 5090 and 46.8 tokens per second on M5 Max. On RTX 4090, it consumes just 0.714 milliwatt-hours per token, 40% more efficient than full-precision 8B models.
Local AI gets practical
With this speed and efficiency, local models can handle coding-agent loops, computer-use workflows, private document analysis, and multimodal debugging. Sensitive tasks stay on device while others escalate to the cloud.
Context window and features
Bonsai 2 27B supports a 262,000-token context window and multimodal text-and-image input. It uses FP16 group-wise scaling for 1.76 effective bits per weight and is released under the Apache 2.0 license.
Implications beyond phones
Low-bit models change the economics of AI across devices, workstations, and datacenters. They fit larger models into the same memory, serve more users on the same hardware, reduce energy per inference, and enable hybrid systems.
Platform support
Bonsai 2 27B runs on NVIDIA GPUs via CUDA and on Apple devices (Mac, iPhone, iPad) via MLX through custom low-bit kernels. Model weights are available today under Apache 2.0 license.
From Caltech to production
PrismML emerged from Caltech researchers and was founded with support from Khosla Ventures, Cerberus, and Google, with continuing support from Samsung. The team has spent years compressing neural networks without sacrificing reasoning ability.
In short
You can now run a capable 27-billion-parameter AI model on your laptop or phone at 5.9GB with 98.2% of the performance of the full-size version.





