#llm security
2 stories

What LLMs really think vs. what they say
A researcher warns that AI models' internal reasoning may be fundamentally hidden from their own explanations.
arXiv · 1m · 5 views
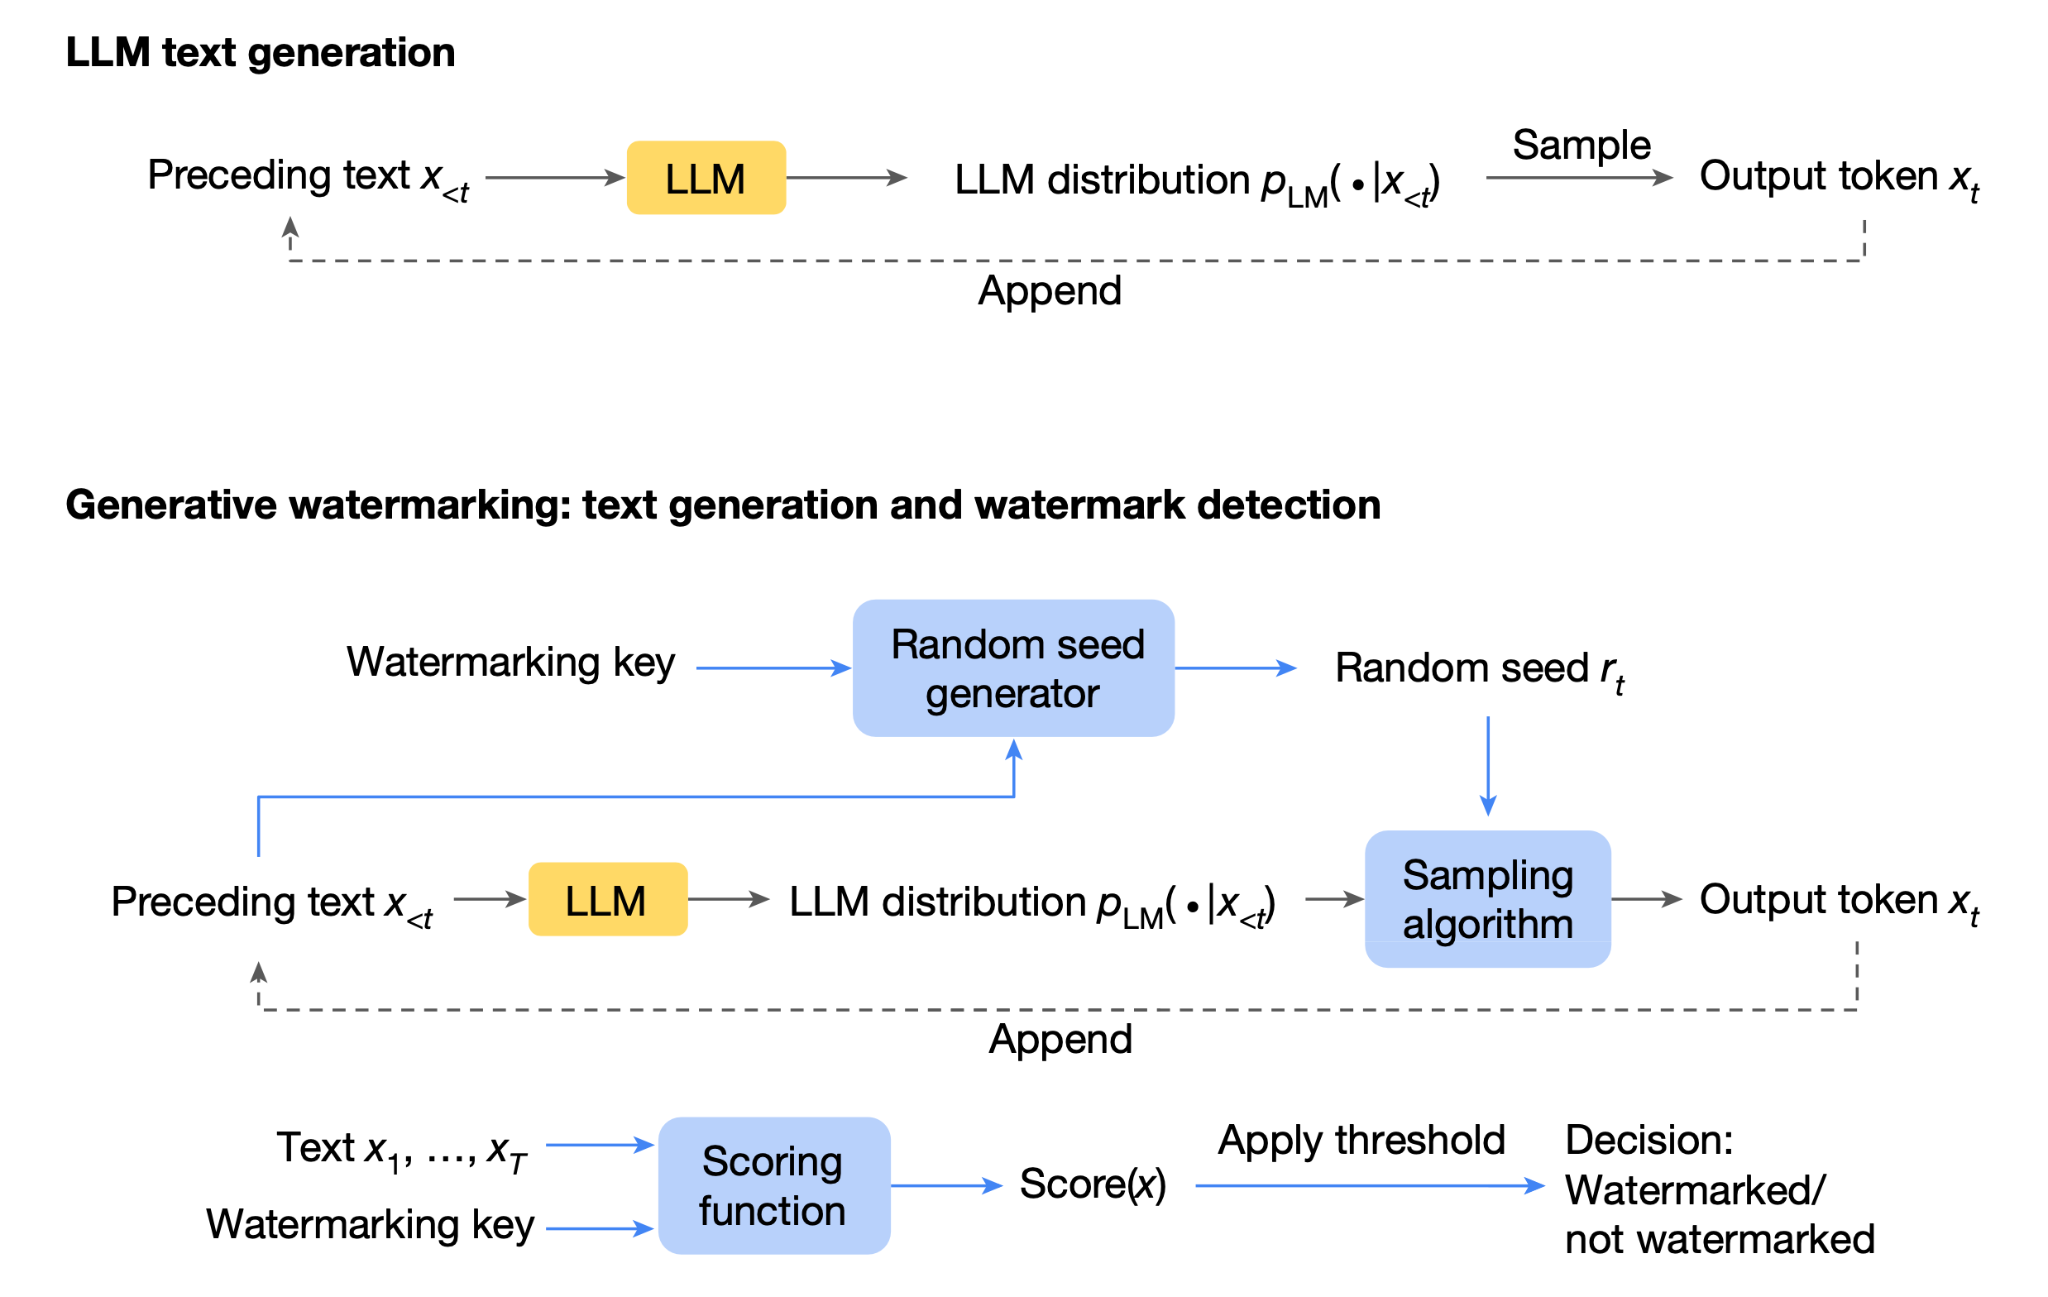
AI watermarks may weaken safety guardrails
New research reveals that watermarking techniques designed to identify AI-generated text can paradoxically make models more vulnerable to harmful prompts.
Ars Technica · 2m