1 story
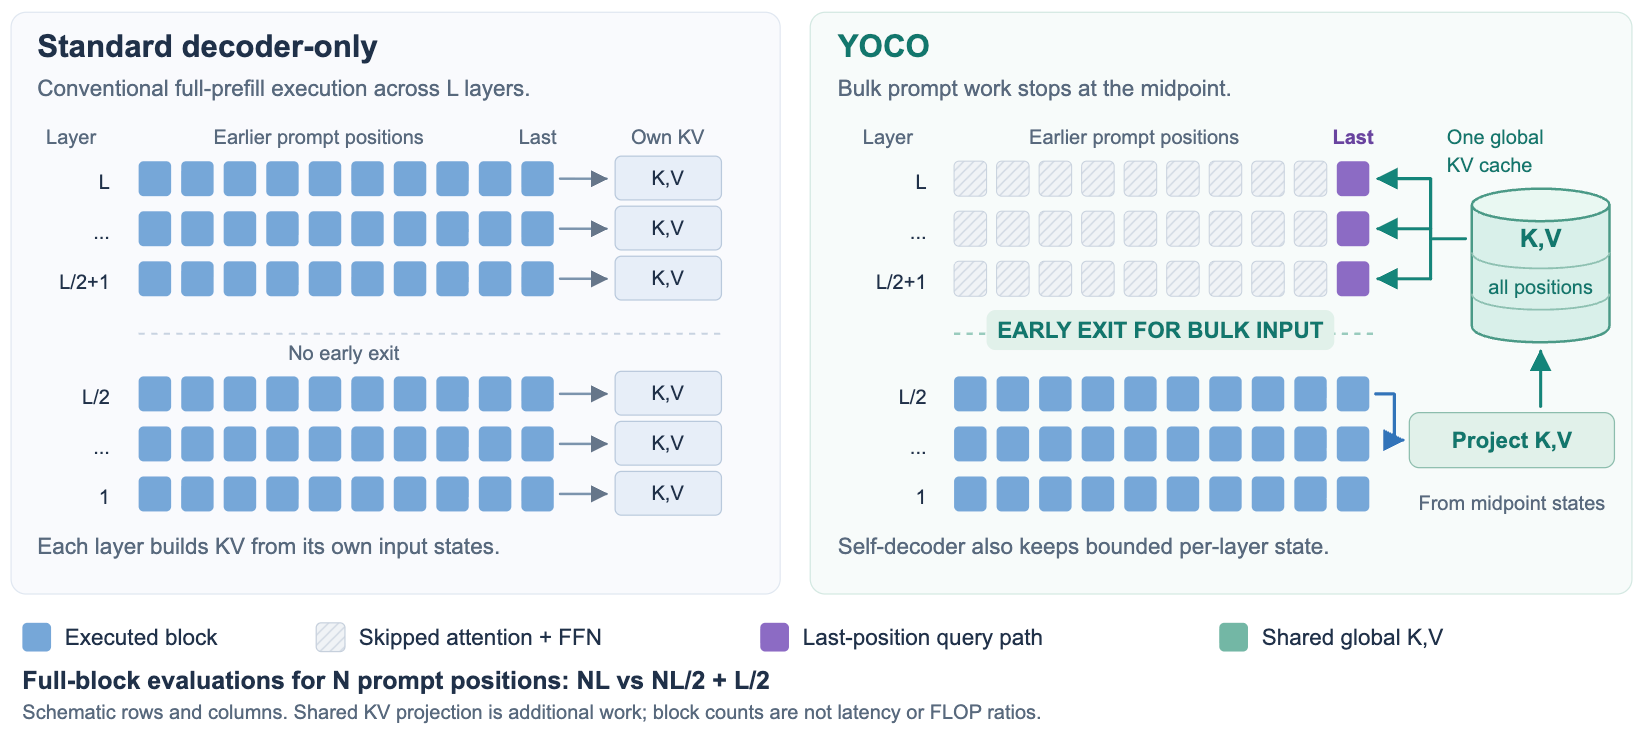
DeepSeek's new model achieves 4x KV cache compression through architectural innovations, enabling faster long-context processing for AI agents.
Github · 3m