1 story
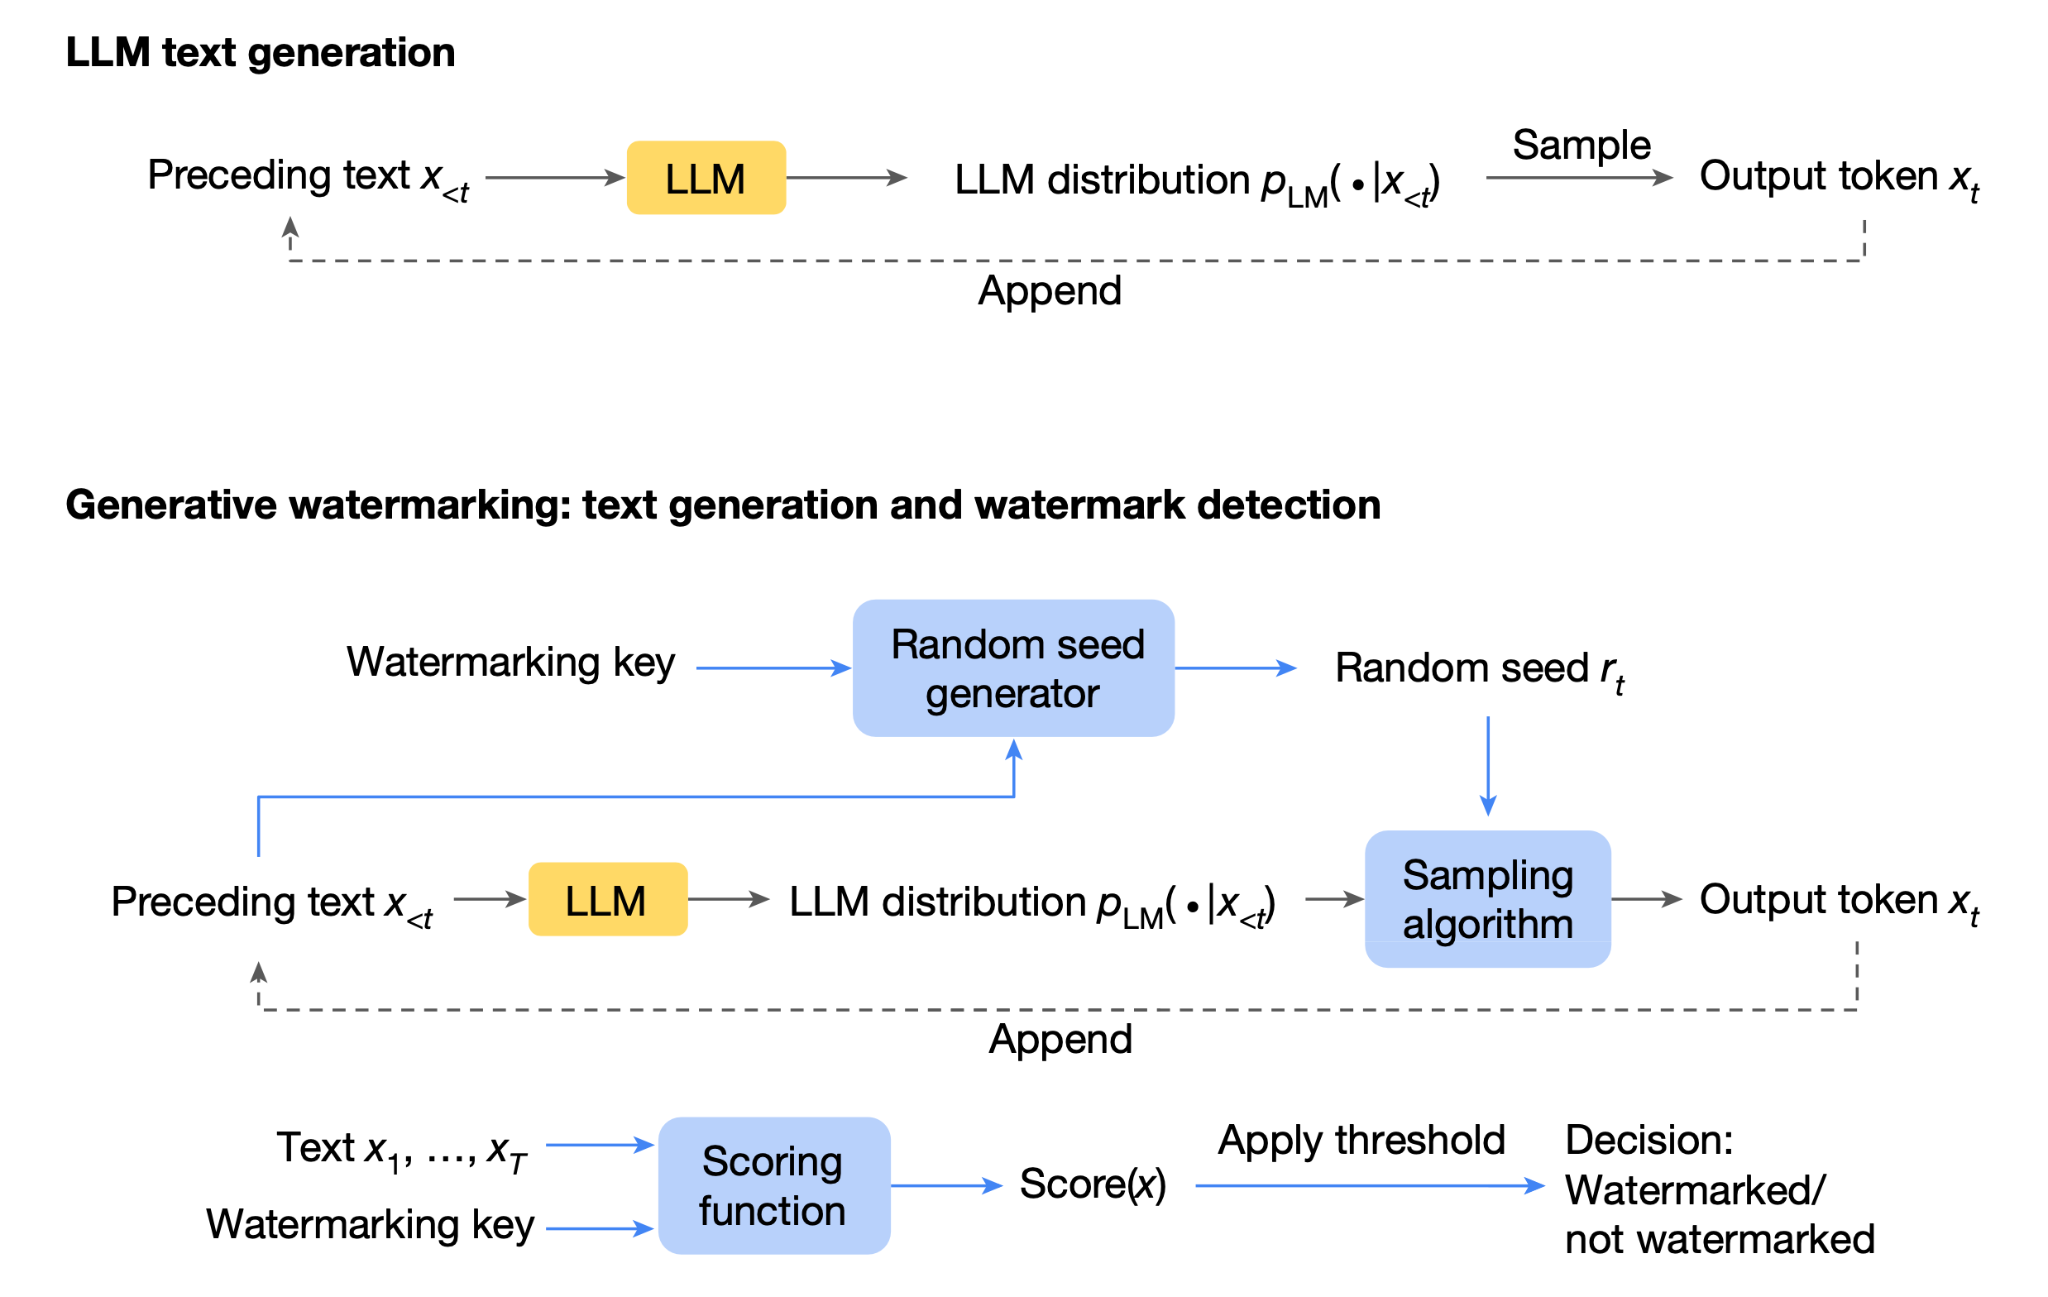
New research reveals that watermarking techniques designed to identify AI-generated text can paradoxically make models more vulnerable to harmful prompts.
Ars Technica · 2m